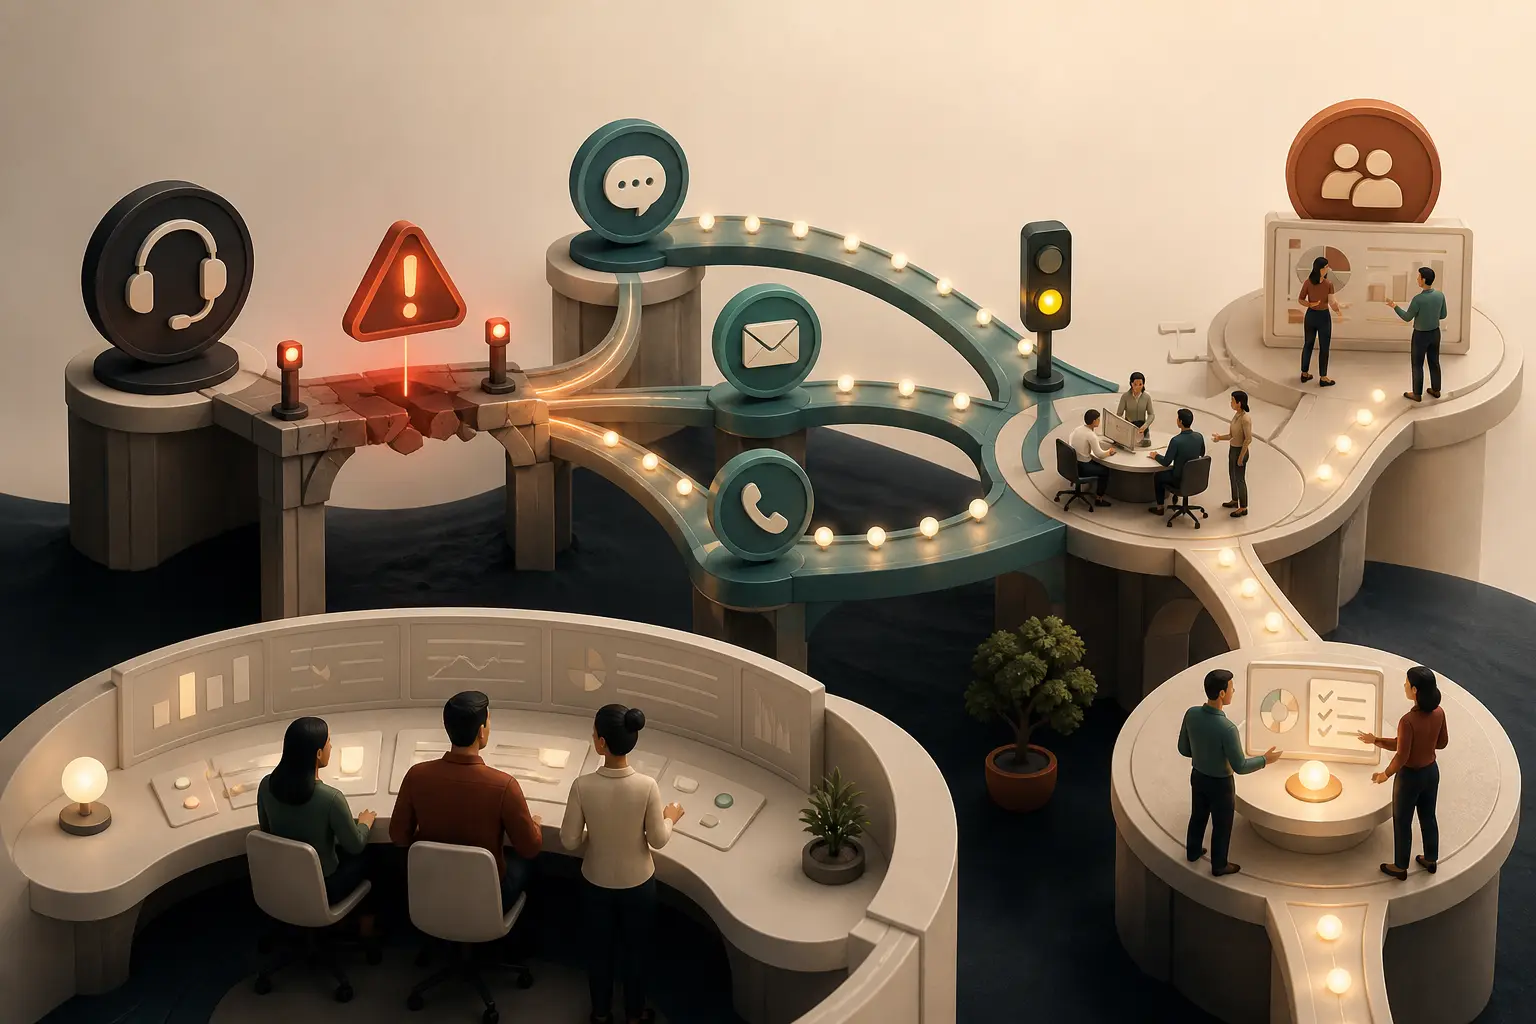
Contingency is not improvising another number during an outage; it preserves ownership, context, and communication until operations recover.
Prioritize services and dependencies
List channels, providers, authentication, webhooks, databases, CRM, knowledge, telephony, power, and essential people. For each workflow, estimate outage impact, accumulating volume, tolerable delay, and alternatives. Not every channel requires the same recovery time.
Analyze the service, not only the system: can a customer report an incident, confirm a commitment, or receive a critical update? Priority depends on the impact to the business and person, not only which component is technically unavailable.
| Element | Decision before failure | Evidence |
|---|---|---|
| Activation | What condition starts contingency? | Alert and confirmation |
| Priority | Which workflow returns first? | Impact and tolerable delay |
| Alternative | Which channel or queue takes over? | Real test |
| Return | When does contingency end? | Reconciliation completed |
Define command, communication, and a minimum queue
Name an incident lead, technical owner, operational lead, and communications owner. Keep a timeline of decisions and status. The alternative channel must be known, accessible, protected, and able to retain the identifier, reason, priority, owner, and next action.
Say what is affected, what remains available, when the next update will arrive, and how urgent cases are handled. Do not declare recovery before end-to-end validation. Avoid making customers repeat everything; recover available context and clearly identify what needs confirmation.
- Incident commander
- Technical and operational contacts
- Tested alternative channel
- Approved status message
- Manual queue with ownership
- Update cadence
Recover, reconcile, and learn
When service returns, test inbound, outbound, attachments, identity, assignment, and reporting. Compare provider events, internal systems, and the alternative queue. Remove duplicates carefully, preserve evidence, and confirm which commitments remain open.
Run a blameless review covering timeline, detection, impact, decisions, communication, recovery, and contributing causes. Turn findings into owners and due dates. Update the plan and test again; an unexercised document quickly becomes unreliable.
How to run a contingency exercise
Start the contingency plan with a small pilot covering one channel, one team, and a defined period. Record the baseline, the rule being tested, the exception owner, and the way back to the previous process. Test normal, ambiguous, duplicate, after-hours, and integration-failure cases before expanding.
During the pilot, compare real events and conversations, not only dashboard averages. Separate process, source, integration, capacity, and execution failures because each requires a different correction. Finish by documenting whether to keep, adjust, expand, or remove the change, publish the approved rule, and schedule the next review.
Keep a concise record of the objective, scope, owner, date, evidence, exceptions, and outcome. Put the approved rule where the team actually works and give the owner authority to correct or stop the flow. This makes the learning independent of one person’s memory and reproducible by another shift or team.
Before expanding, run a short review with service, management, and the people who maintain the involved systems. Confirm that the customer receives an understandable answer, the team can see current ownership, and reporting reflects the same event visible in the conversation. If these three views disagree, the pilot is not finished.
Continue with Centralize channels without losing context, Operations audit and Prioritize the backlog. Use the guides together so process, technology, and management evolve from the same operating definition.
- Critical processes and dependencies mapped
- Observable activation criterion
- Owners and contacts are current
- Alternative channel and minimum queue tested
- Audience-specific communication prepared
- Return requires end-to-end validation
- Reconciliation and post-incident review complete