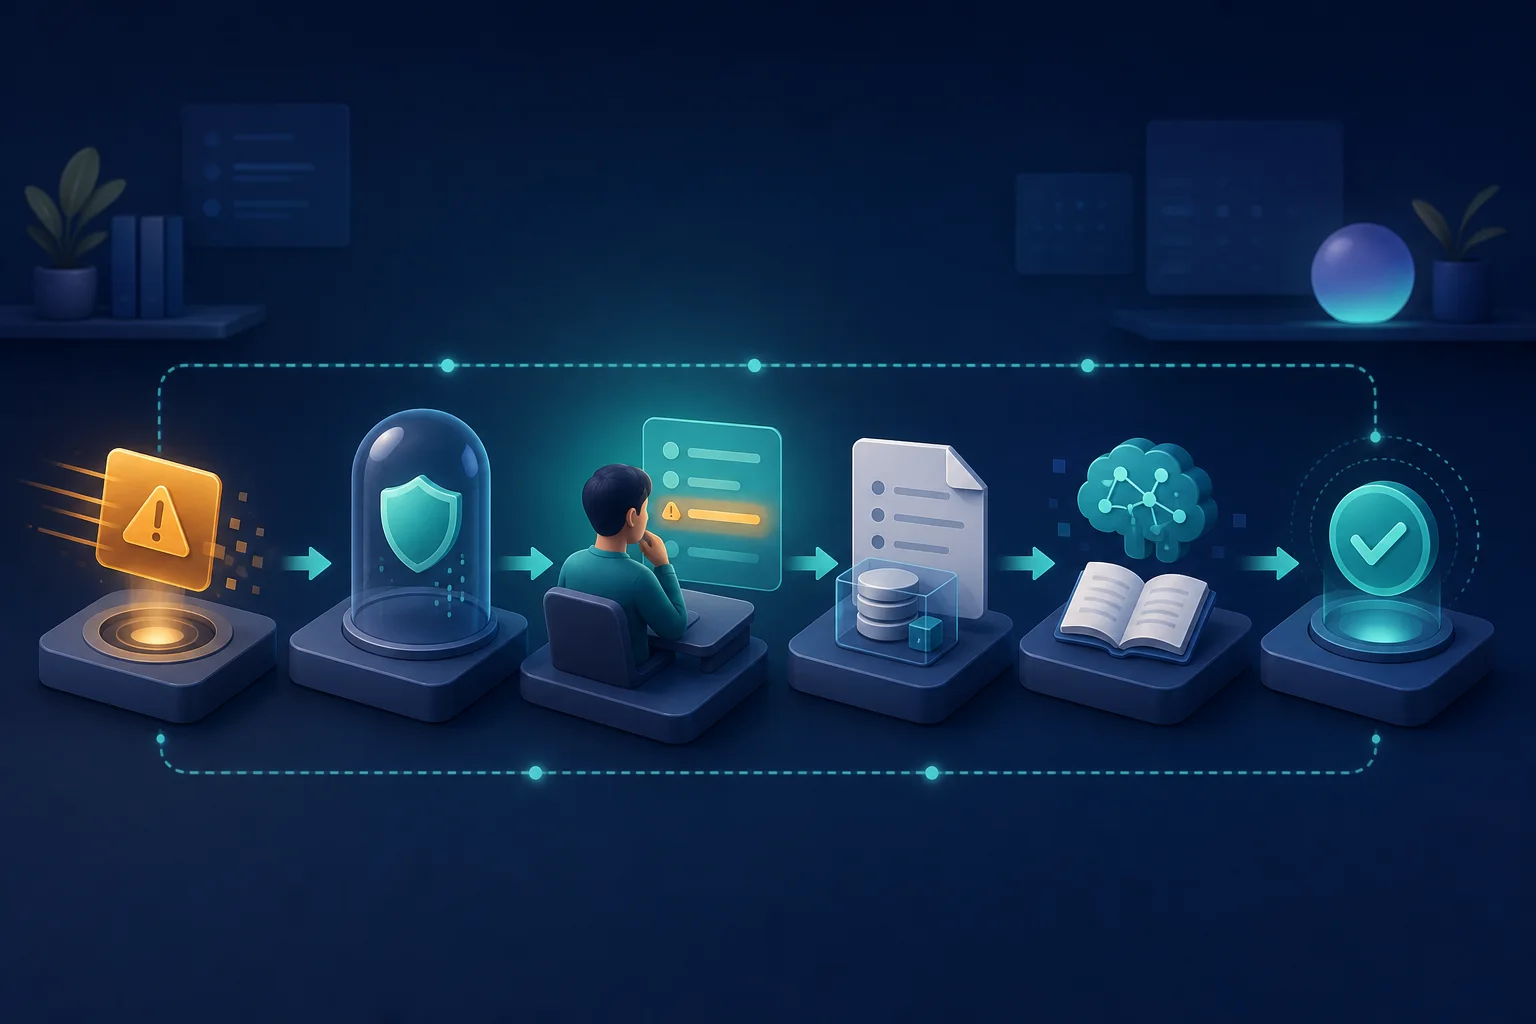
When customer-service AI gives a wrong answer, the first move is not a rushed prompt rewrite. Limit the affected path according to risk, assign a human owner to the conversation, correct the information for the customer, preserve the context that produced the failure, and only then investigate the cause.
Not every poor reply is an incident—but every failure needs an owner
An awkward sentence can enter the normal improvement queue. A reply that invents a price, deadline, or policy; exposes data; claims an action that did not happen; blocks human help; or influences a sensitive decision deserves incident treatment. The deciding factors are potential impact, reversibility, and exposure—not how strange the wording sounds.
The NIST AI Risk Management Framework covers post-deployment monitoring, appeal and override, incident response, recovery, and change management. It also calls for incidents and errors to be tracked, communicated, and documented. In service operations, that means the customer needs a human route while the business needs enough evidence to reconstruct what happened.
Open a record with the time, channel, contact reason, owner, and provisional severity. Do not wait for a perfect root cause before assigning ownership. Classification can change; responsibility should not remain empty.
Use severity to choose the right containment
A single response for every AI error is either too weak or too disruptive. This table is an operational synthesis, not an official or legal classification; tailor it to your risks and obligations.
| Level | Operational example | Initial containment |
|---|---|---|
| Low | Poor tone or incomplete guidance, with no action and an easy correction | Take over, correct the reply, and add it to scheduled review |
| Moderate | Wrong policy, deadline, or guidance that could change a customer's decision | Disable the affected answer or intent and search for similar cases |
| High | Wrong action, exposed data, improper authorisation, or hard-to-reverse harm | Pause the relevant workflow, involve internal owners, and address affected people |
| Critical | Repeated or widespread failure with immediate risk to people, rights, security, or operations | Stop the affected capability and use the formal crisis, security, privacy, or continuity plan |
Containment does not always mean disabling all AI. It can mean removing one source, blocking one tool, routing a contact reason straight to people, or temporarily using approved fixed replies. The scope must be broad enough to prevent repetition and narrow enough to keep safe paths available.
- Identify the affected workflow, intent, channel, and version
- Confirm whether the failure involved only text or also an action
- Assign a human owner and a follow-up queue
- Preserve evidence before changing a source, prompt, or integration
- Search for the same pattern beyond the reported conversation
- Name the person who can authorise recovery
A seven-step response workflow
- Receive: record the report from a customer, agent, monitor, or audit without asking the person to prove the technical cause.
- Own: put a named person into the conversation with the available history. Confirm the next step and avoid serial transfers.
- Contain: limit the reply, source, action, or automation related to the observed risk. If scope is unclear, begin conservatively and refine using evidence.
- Correct: state what information or action was wrong, provide the verified current state, and explain what happens next. Do not present a hypothesis as a correction.
- Scope: find other conversations exposed to the same version, source, intent, or tool. Keep potential exposure separate from confirmed impact.
- Investigate: classify the cause and fix the correct layer. Define an exit test before editing.
- Recover: test ordinary, edge, and original cases, release to a controlled scope, and watch for recurrence.
NIST SP 800-61 Revision 3 integrates preparation, detection, response, and recovery into risk management. It is cybersecurity incident guidance rather than a chatbot manual, but the discipline helps teams avoid mistaking symptom removal for safe service recovery.
Preserve evidence and fix the right layer
Before changing anything, retain only the information needed under controlled access: the customer message, generated reply, retrieved source, applicable instructions, model and workflow version, tools called, returned results, timestamp, and conversation state. Do not duplicate personal data into loose spreadsheets simply to make analysis convenient.
| Signal | Possible cause to verify | Potential correction |
|---|---|---|
| The reply cites a rule that does not exist | Missing, outdated, or wrongly retrieved knowledge | Correct the knowledge base, ownership, version, and retrieval criteria |
| The correct source was present, but the AI overreached | Ambiguous instruction, poor example, or scope that is too broad | Constrain behaviour and add a prohibited example to the test set |
| It claimed success, but the action failed | Integration, timeout, parsing, or confirmation failure | Require system confirmation before communicating completion |
| It continued when it should have stopped | A confidence limit or risk signal did not trigger | Review fallback and stop conditions |
| It handed off without context or ownership | An incomplete handoff contract | Apply the human handoff checklist |
One conversation can expose several causes. Avoid using “model hallucination” as a catch-all diagnosis: it does not tell the organisation whether to repair knowledge, permissions, integration, prompts, routing, or supervision.
Correct the customer and define recovery criteria
Communication should be proportional and truthful. Identify the incorrect information, provide a verified correction, clarify whether an action actually took place, and provide a responsible contact. Where an impact invokes formal privacy, security, compliance, or specialist-support processes, follow your organisation's owners and applicable timelines; this playbook is not legal advice.
Do not reactivate a workflow because “the prompt looks better.” Before recovery, confirm that:
- the original case now gets the expected answer or handoff;
- similar and boundary cases have been tested;
- the correction did not expand data access or action permissions;
- the operational owner has accepted the residual risk;
- a signal exists to detect recurrence;
- the release can be stopped without losing conversation context.
Start with controlled exposure, inspect real conversations, and retain a human route. Recovery ends when operations confirm stability in the live context—not when someone publishes the change.
Turn every incident into a regression test
The report, wrong output, and expected correction form an evaluation case. Remove unnecessary data, preserve the condition that triggered the failure, and record the behaviour that must never recur. Run the case alongside ordinary examples so a narrow correction does not break the rest of the workflow.
OpenAI's official guidance on contextual evals recommends specifying desired behaviour, measuring under realistic conditions, and improving through error analysis. It also recommends continuous measurement after launch. Combine regression cases with a regular AI conversation audit: incidents surface acute failures, while routine samples can identify patterns before they become severe.
Close the record with cause, affected people or workflows, decisions, correction, tests, approver, and follow-up signals. Before expanding again, return to a controlled pilot with shadow mode, go/no-go gates, and rollback. The objective is not to promise that AI will never be wrong. It is to ensure the operation can detect, contain, correct, and learn in a traceable way.